






ONES 3.1: Real-Time Compute & GPU Observability for High-Performance Workloads
Unified, vendor-agnostic telemetry across NICs, GPUs, CPUs, memory, and storage—so you can find bottlenecks fast, prevent failures, and keep AI/HPC clusters humming.
AI and HPC stacks move fast—and so do problems. ONES delivers deep, real-time telemetry across compute and I/O: NICs, GPUs, CPUs, SSDs, and more. With seamless multi-vendor support and a single operational view, teams shift from reactive firefighting to proactive performance management.
Unified Monitoring for Compute, NICs, and GPUs
ONES correlates host, accelerator, and network telemetry to expose the full data path—from PCIe and memory to link layers—so operators can pinpoint the real culprit behind latency, loss, or throttling.
NIC Insights
Ensure clean, reliable links with interface-level visibility: administrative/oper status, MTU, port speed, and auto-negotiation. Track FEC modes for resiliency, and analyze LLDP counters (TX/RX/discards) to validate topology and catch cabling or configuration drift early.
GPU & Compute Performance Monitoring
Bottlenecks can originate in the host or the GPU. ONES observes both, surfacing hot spots and imbalance across nodes, devices, and time windows.
Compute Health Monitoring
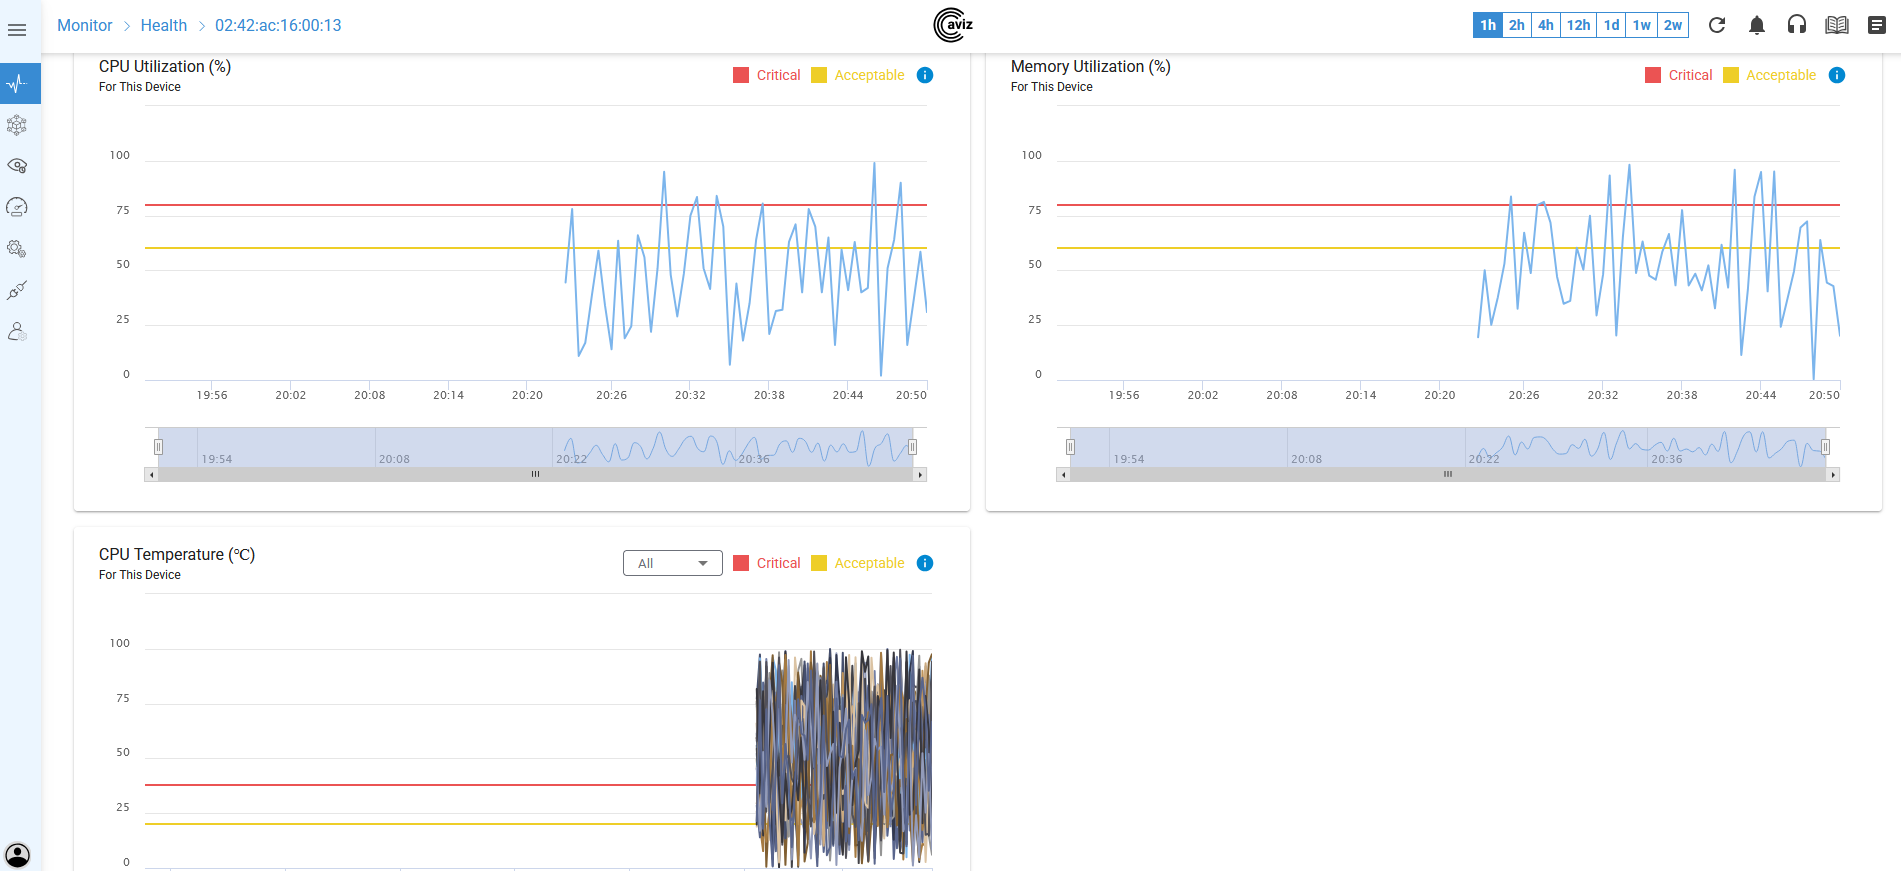
Continuously track CPU utilization, memory pressure, temperature, platform metadata, and uptime. Proactive thresholds and trend views help prevent thermal throttling and resource starvation before workloads degrade.
GPU Performance Insights
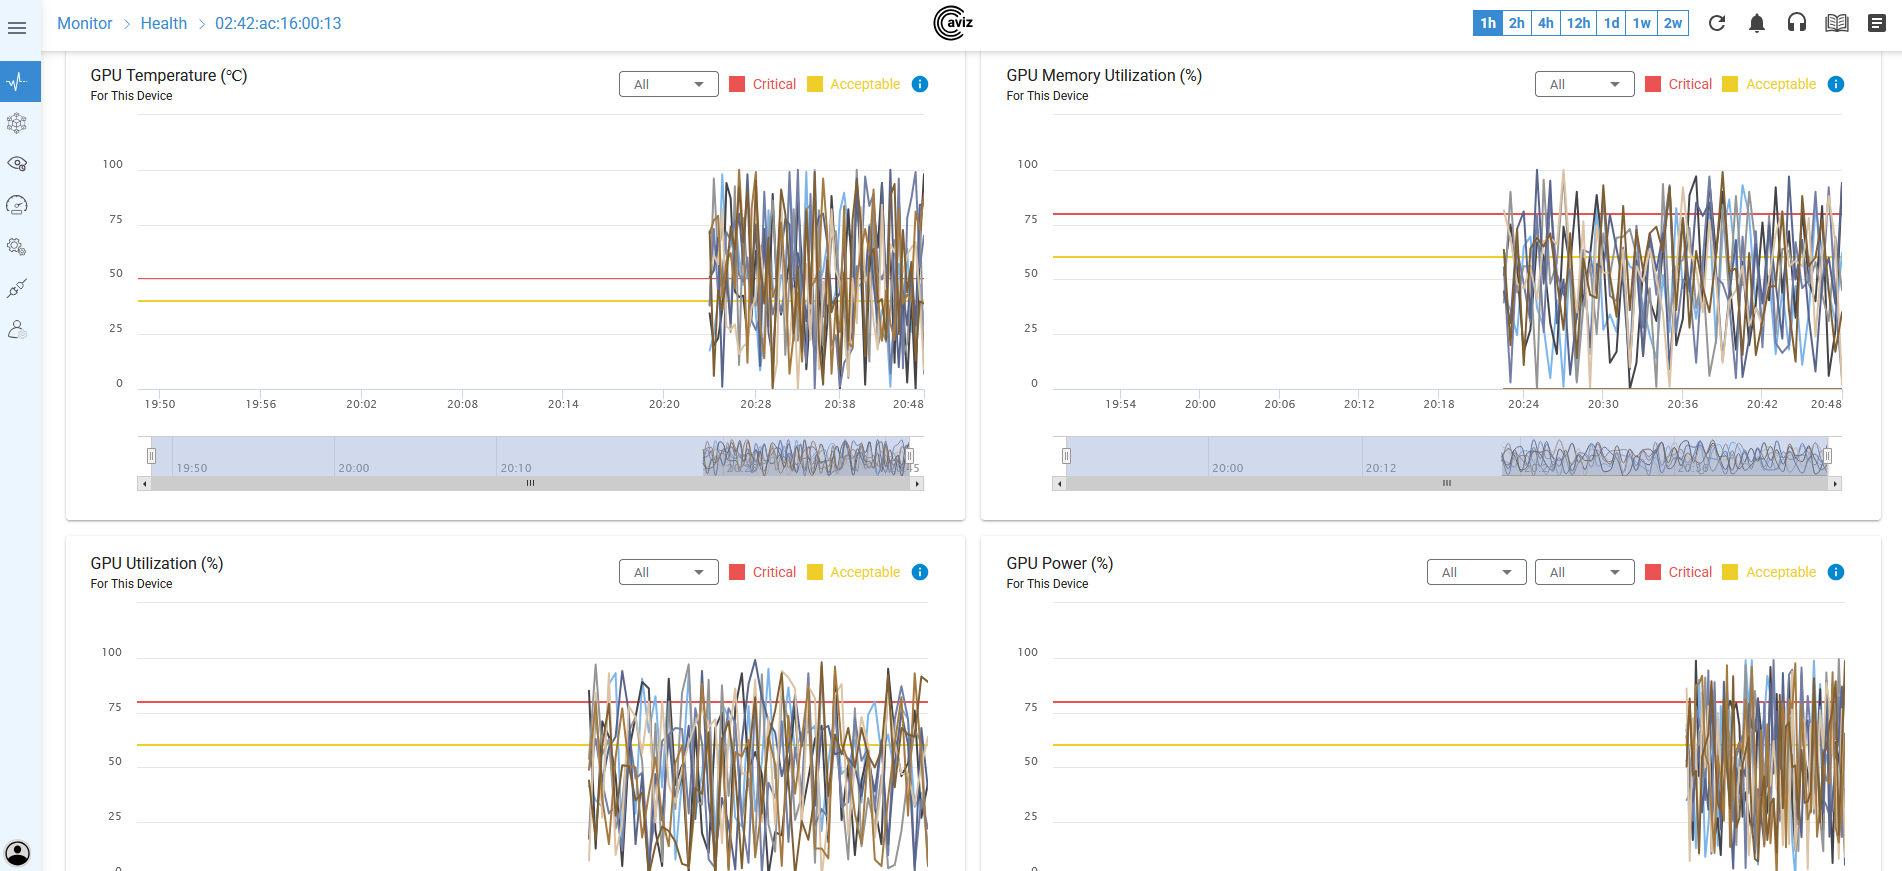
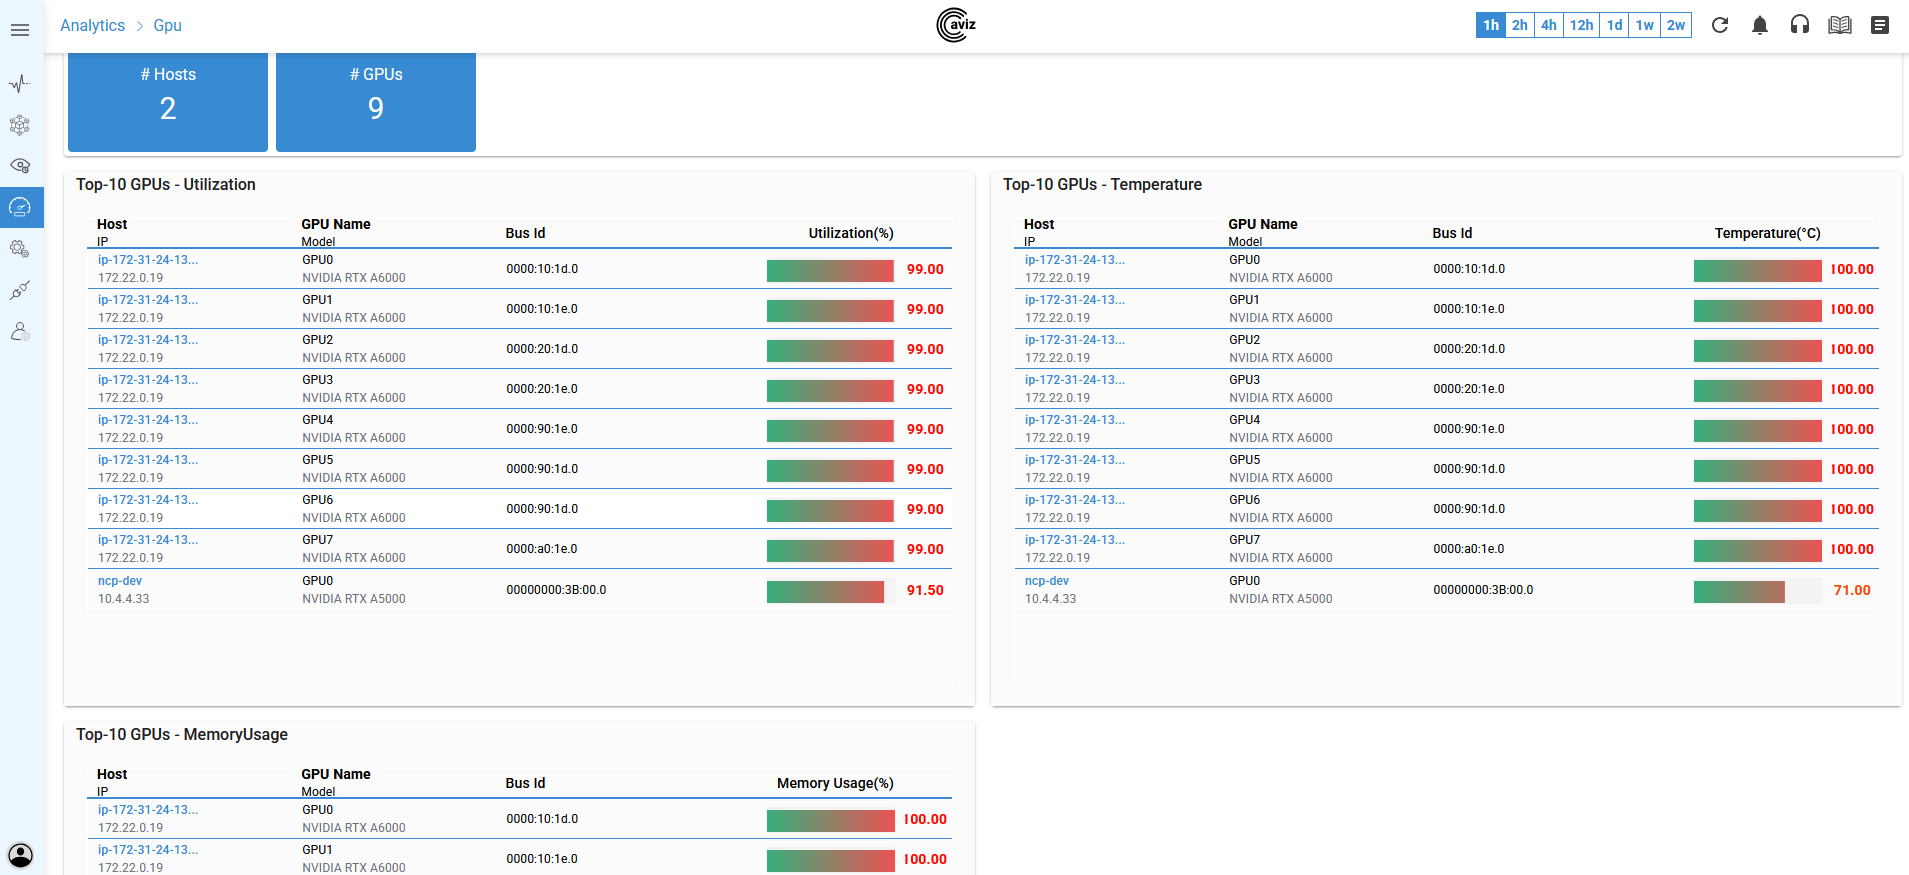
Using NVIDIA SMI, ONES captures GPU temperature, utilization, power draw, memory allocation, bus ID, and serial number. Correlate power and thermal spikes with workload phases to optimize placement and reduce failures.
CPU & Memory Utilization
Monitor CPU load across intervals and memory usage at both host and GPU levels. Combine with uptime to assess stability, schedule maintenance, and harden SLAs for training and inference windows.
Storage & Platform Health
Stay ahead of I/O slowdowns with disk health and utilization metrics—used %, absolute usage (MB), temperature, and health state— alongside chassis/platform indicators for a complete view of node readiness.

Vendor-Agnostic & Built to Scale
ONES collects via standard Linux interfaces and supports multiple NIC vendors (e.g., Intel, Mellanox/NVIDIA). Designed for large-scale fleets, it centralizes monitoring across servers hosting GPUs, NICs, and individual GPUs—without overloading resources or locking you to a single hardware stack.
Conclusion
With unified, real-time telemetry across compute, accelerators, storage, and links, ONES 3.1 helps teams optimize performance, prevent failures, and run multi-vendor AI/HPC environments with confidence.


